Internal:CDT3D GPU Smoothing: Difference between revisions
Jump to navigation
Jump to search
Spyridon97 (talk | contribs) |
Spyridon97 (talk | contribs) |
||
| Line 26: | Line 26: | ||
###### Original point value on GPU, grid(1) block(1) | ###### Original point value on GPU, grid(1) block(1) | ||
###### Grid creation on GPU, grid(1) block(1) | ###### Grid creation on GPU, grid(1) block(1) | ||
###### Grid point values using global values array on GPU, grid(2, 2, 2) block(4, 4, 4) | ###### Grid point values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4) | ||
###### Reduction using global values array on GPU, grid(1) block(1) | ###### Reduction using global values array(512) on GPU, grid(1) block(1) | ||
##### Time total = 18.563 sec | ##### Time total = 18.563 sec | ||
###### CPU = 0.79182 sec | ###### CPU = 0.79182 sec | ||
| Line 36: | Line 36: | ||
###### MemCopyH2D = 0.12792 sec | ###### MemCopyH2D = 0.12792 sec | ||
###### MemCopyD2H = 0.00002 sec | ###### MemCopyD2H = 0.00002 sec | ||
#### Version 2 (copy what you need): | |||
##### Steps: | |||
###### Bounding box on CPU | |||
###### Grid creation on CPU | |||
###### Grid point values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4) | |||
###### Reduction using global values array(512) on GPU, grid(1) block(1) | |||
###### Original point value on CPU concurrently with steps 3 & 4 | |||
##### Time total = 10.8227 sec | |||
###### CPU = 1.8857 sec | |||
###### Step 3 = 6.47006 sec | |||
###### Steo 4 = 1.74147 sec | |||
###### MemCopyH2D = 0.37493 sec | |||
###### MemCopyD2H = 0.15225 sec | |||
#### Version 3 (copy what you need): | |||
##### Steps: | |||
###### Bounding box on CPU | |||
###### Grid creation on CPU | |||
###### Grid point values using global values and ids arrays(8+8) and reduction for the max value and id of a block on GPU, grid(8) block(64) | |||
###### Reduction using global values and ids arrays(8+8) on GPU, grid(1) block(8) | |||
###### Original point value on CPU concurrently with steps 3 & 4 | |||
##### Time total = 9.17189 sec | |||
###### CPU = 2.04448 sec | |||
###### Step 3 = 6.40427 sec | |||
###### Steo 4 = 0.19378 sec | |||
###### MemCopyH2D = 0.37604 sec | |||
###### MemCopyD2H = 0.15332 sec | |||
### Parallel CPU-wise: | ### Parallel CPU-wise: | ||
Revision as of 00:04, 17 March 2021
Presentations
Spring 2021
- A Unified Approach for Parallel Mesh Operations by Christos✔
- GPU Architecture ✔
Code
Spring 2021
- Discrete Mesh Optimization using the paper: Discrete Mesh Optimization on GPU, The results below are using the tet_shape metric from the Verdict library
- CPU version:
- Sequential:
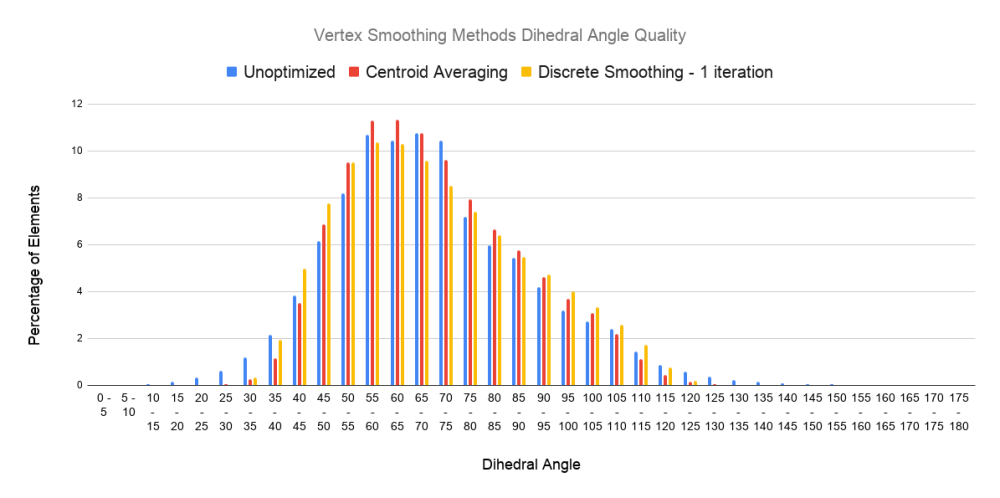
- Dihedral Quality of different smoothing methods:✔
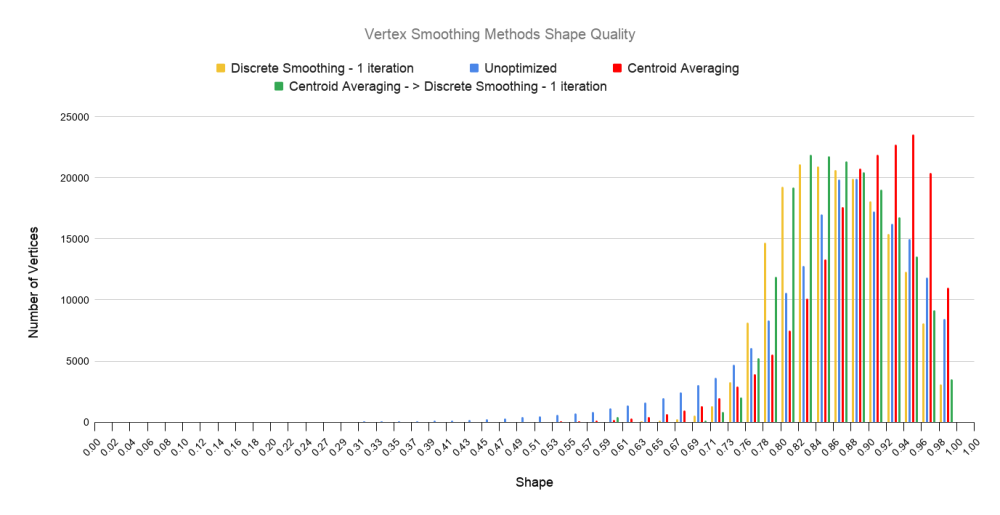
- Shape Quality of different smoothing methods:✔
- Dihedral Quality of different smoothing methods:✔
- Parallel:
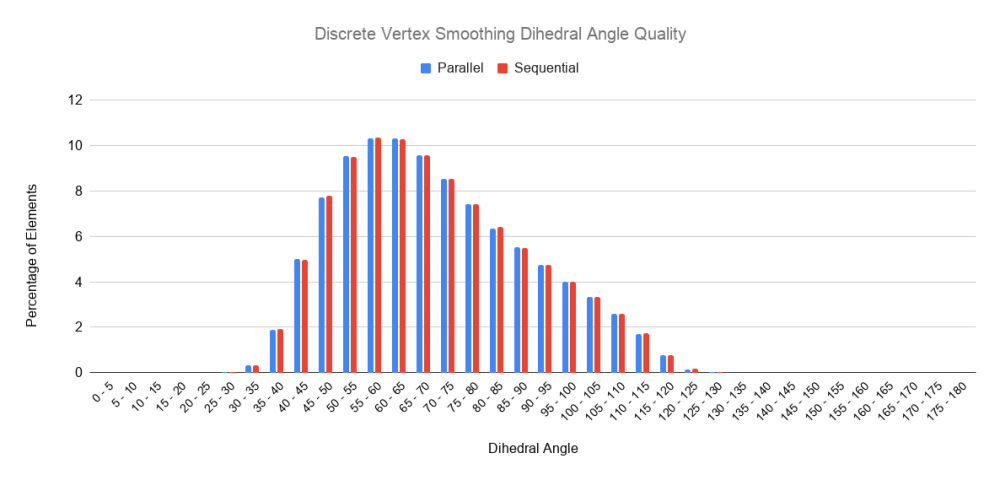
- Dihedral Quality: Sequential vs Parallel:✔
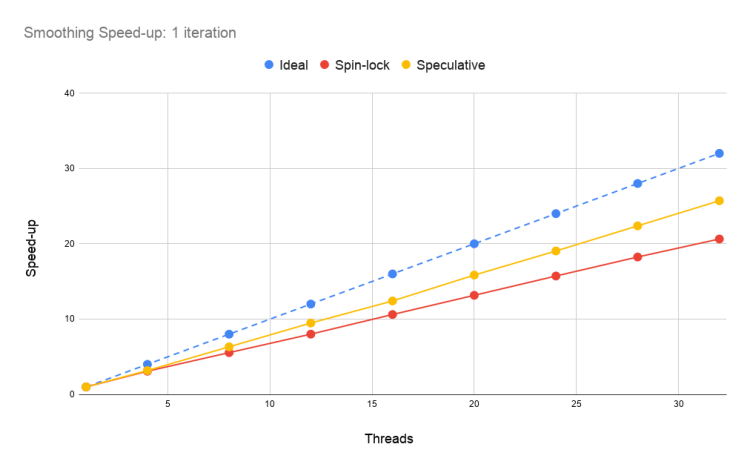
- Speed-Up:✔
- RollBacks✔:

- Dihedral Quality: Sequential vs Parallel:✔
- Sequential:
- GPU version:
- Sequential CPU-wise:
- Version 1 (all points copied):
- Steps:
- Bounding box on GPU, grid(1) block(1)
- Original point value on GPU, grid(1) block(1)
- Grid creation on GPU, grid(1) block(1)
- Grid point values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4)
- Reduction using global values array(512) on GPU, grid(1) block(1)
- Time total = 18.563 sec
- CPU = 0.79182 sec
- Steps 1 & 2 = 8.31743 sec
- Step 3 = 1.03768 sec
- Step 4 = 6.55488 sec
- Steo 5 = 1.73327 sec
- MemCopyH2D = 0.12792 sec
- MemCopyD2H = 0.00002 sec
- Steps:
- Version 2 (copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Grid point values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4)
- Reduction using global values array(512) on GPU, grid(1) block(1)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 10.8227 sec
- CPU = 1.8857 sec
- Step 3 = 6.47006 sec
- Steo 4 = 1.74147 sec
- MemCopyH2D = 0.37493 sec
- MemCopyD2H = 0.15225 sec
- Steps:
- Version 3 (copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Grid point values using global values and ids arrays(8+8) and reduction for the max value and id of a block on GPU, grid(8) block(64)
- Reduction using global values and ids arrays(8+8) on GPU, grid(1) block(8)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 9.17189 sec
- CPU = 2.04448 sec
- Step 3 = 6.40427 sec
- Steo 4 = 0.19378 sec
- MemCopyH2D = 0.37604 sec
- MemCopyD2H = 0.15332 sec
- Steps:
- Version 1 (all points copied):
- Sequential CPU-wise:
- CPU version:


- Parallel CPU-wise: