Internal:CDT3D GPU Smoothing: Difference between revisions
Jump to navigation
Jump to search
Spyridon97 (talk | contribs) |
Spyridon97 (talk | contribs) m Spyridon97 moved page Internal:CDT3D to Internal:CDT3D GPU Smoothing |
||
| (11 intermediate revisions by the same user not shown) | |||
| Line 149: | Line 149: | ||
###### Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16) | ###### Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16) | ||
###### Original point value on CPU concurrently with steps 3 & 4 | ###### Original point value on CPU concurrently with steps 3 & 4 | ||
### Parallel | ##### Time: | ||
###### lock time: 0.0190836 sec | |||
###### findCavityCells time: 0.178939 sec | |||
###### findUniqueVertices time: 0.215159 sec | |||
###### dataCollection time: 0.187204 sec | |||
###### boundingBox time: 0.0280833 sec | |||
###### grid time: 0.00122939 sec | |||
###### originalPointValue time: 0.12965 sec | |||
###### assignNewPoint time: 0.00165265 sec | |||
###### unlock time: 0.0117685 sec | |||
###### Total Cpu time: 0.77277 sec | |||
### Parallel CPU-wise: | |||
#### Version 4: | #### Version 4: | ||
##### Speed-Up:✔<br>[[File:Smoothing_Speed-up-heterogeneous.png|750px|Smoothing_Speed-up-heterogeneous.png]] | ##### Speed-Up:✔<br>[[File:Smoothing_Speed-up-heterogeneous.png|750px|Smoothing_Speed-up-heterogeneous.png]] | ||
##### Rollbacks-Time-Per-Thread:✔<br>[[File:parallel.v4.png|750px|parallel.v4.png]] | ##### Rollbacks-Time-Per-Thread:✔<br>[[File:parallel.v4.png|750px|parallel.v4.png]] | ||
##### Profiler: 4 cpu threads, 4 streams✔<br> [[File:profiler.v4.png|750px|profiler.v4.png]] | |||
#### Version 4.1: | |||
##### Profiler: 2 cpu threads, 2(copy)+8(computation) streams✔<br> [[File:profiler.v4.1.png|750px|profiler.v4.1.png]] | |||
#### Version 4.2: | #### Version 4.2: | ||
##### Rollbacks-Time-Per-Thread:✔<br>[[File:parallel.v4.2.png|750px|parallel.v4.2.png]] | ##### Rollbacks-Time-Per-Thread (#vertices = 28,217):✔<br>[[File:parallel.v4.2.png|750px|parallel.v4.2.png]] | ||
##### Rollbacks-Time-Per-Thread (#vertices = 79,809):✔<br>[[File:parallel.v4.2-double-size.png|750px|parallel.v4.2-double-size.png]] | |||
###### CPU (1 thread) 666 sec, CPU (32 threads) 28.29 sec | |||
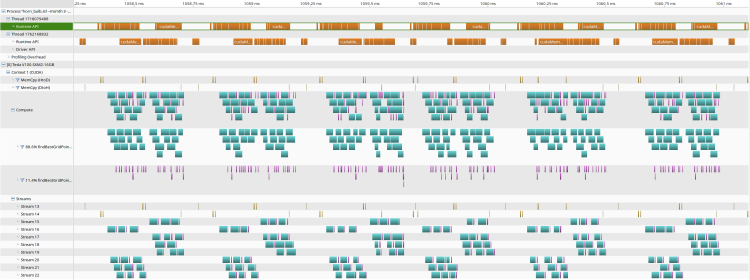
##### Profiler: 2 cpu threads, 2(copy)+8(computation) streams✔<br> [[File:profiler.v4.2.png|750px|profiler.v4.2.png]] | |||
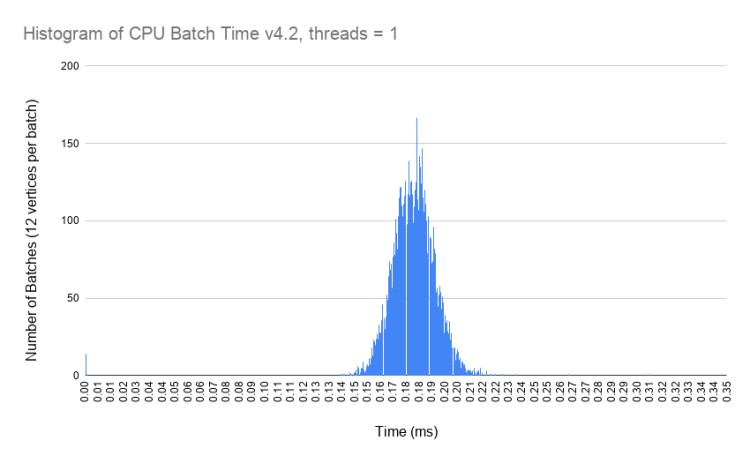
##### CPU Time Histogram 1 thread:✔<br>[[File:Histogram_of_CPU_Batch_Time_v4.2_threads=1.png|750px|Histogram_of_CPU_Batch_Time_v4.2_threads=1.png]] | |||
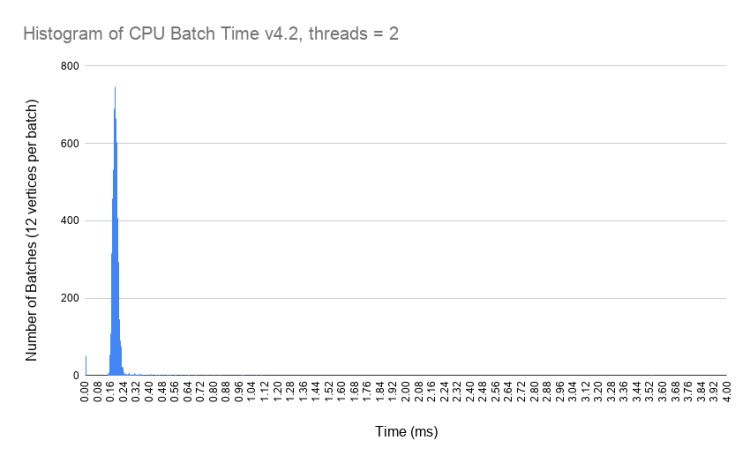
##### CPU Time Histogram 2 threads:✔<br>[[File:Histogram_of_CPU_Batch_Time_v4.2_threads=2.png|750px|Histogram_of_CPU_Batch_Time_v4.2_threads=2.png]] | |||
Latest revision as of 16:15, 14 April 2021
Presentations
Spring 2021
- A Unified Approach for Parallel Mesh Operations by Christos✔
- GPU Architecture ✔
Code
Spring 2021
- Discrete Mesh Optimization using the paper: Discrete Mesh Optimization on GPU, The results below are using the tet_shape metric from the Verdict library
- CPU version:
- Sequential:
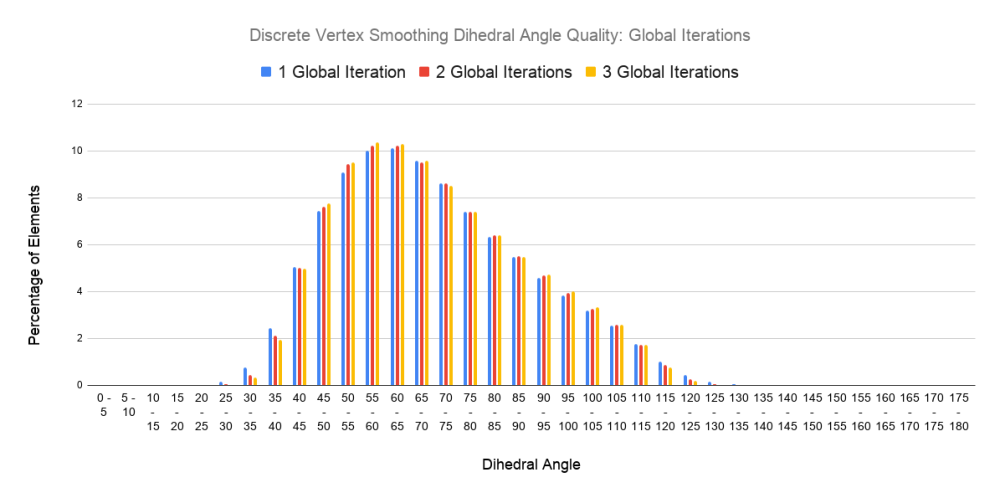
- Dihedral Quality of Discrete Vertex smoothing with Global Iterations:✔
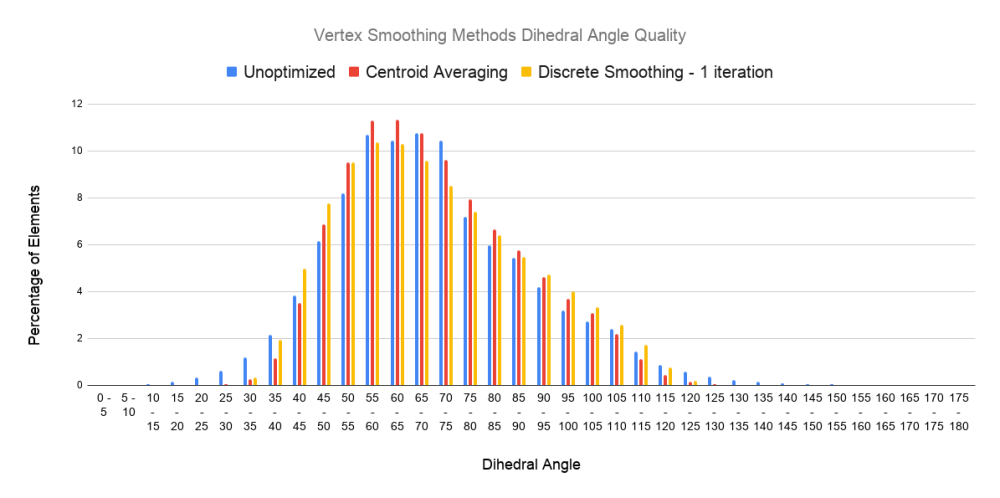
- Dihedral Quality of different smoothing methods:✔
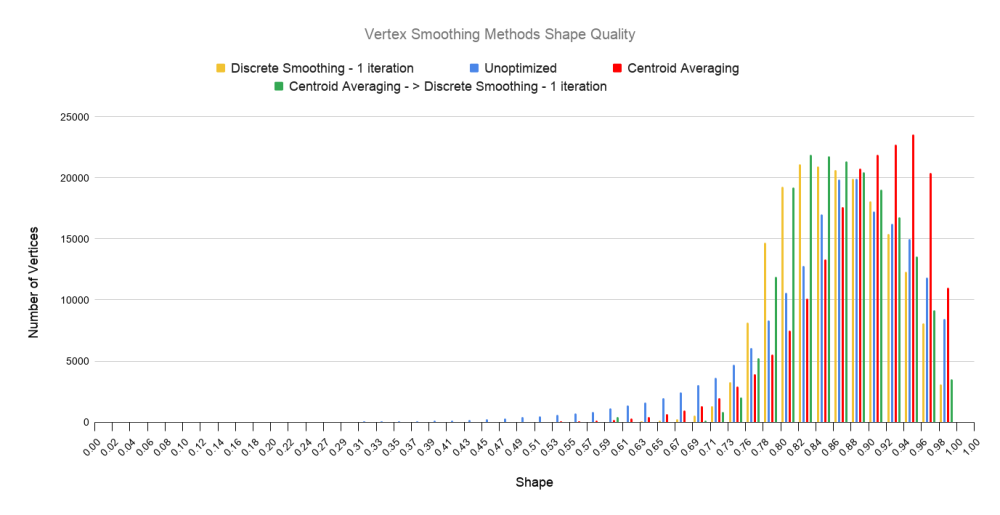
- Shape Quality of different smoothing methods:✔
- Distribution of Smoothing Time Per Vertex:✔

- Dihedral Quality of Discrete Vertex smoothing with Global Iterations:✔
- Parallel:
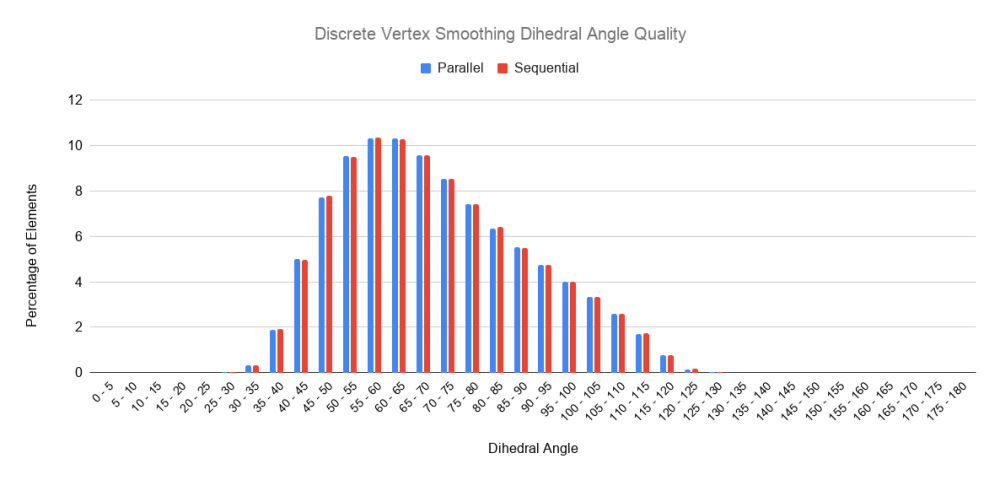
- Dihedral Quality: Sequential vs Parallel:✔
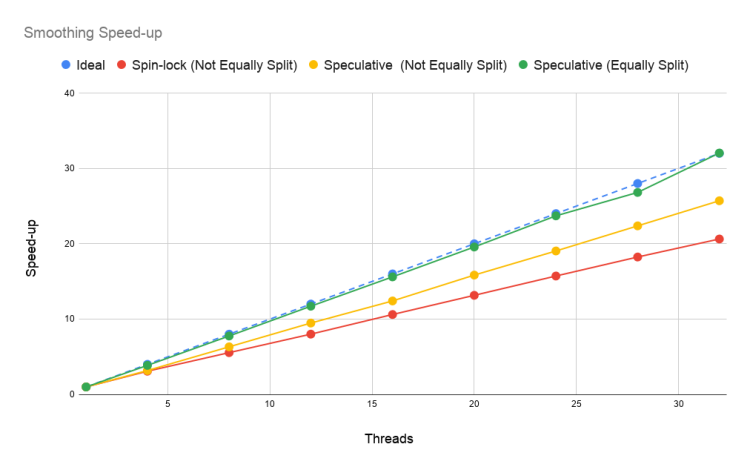
- Speed-Up:✔
- RollBacks✔:

- Dihedral Quality: Sequential vs Parallel:✔
- Sequential:
- GPU version:
- Sequential CPU-wise:
- Distribution of Smoothing Time Per Vertex:✔

- Version 1 (all points copied):
- Steps:
- Bounding box on GPU, grid(1) block(1)
- Original point value on GPU, grid(1) block(1)
- Grid creation on GPU, grid(1) block(1)
- Gridpoint values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4)
- Reduction using global values array(512) on GPU, grid(1) block(1)
- Time total = 18.563 sec (90 sec on CPU sequential)
- CPU = 0.79182 sec
- Steps 1 & 2 = 8.31743 sec
- Step 3 = 1.03768 sec
- Step 4 = 6.55488 sec (per point)
- Step 5 = 1.73327 sec
- MemCopyH2D = 0.12792 sec
- MemCopyD2H = 0.00002 sec
- Steps:
- Version 2.0 (copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4)
- Reduction using global values array(512) on GPU, grid(1) block(1)
- !!! Note: access global memory multiple times !!!
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 15.06656 sec
- CPU = 1.8857 sec (all cavities)
- Step 3 = 6.43994 sec
- Step 4 = 6.20552 sec
- MemCopyH2D = 0.38211 sec
- MemCopyD2H = 0.15329 sec
- Steps:
- Version 2.1 (copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values array(512) on GPU, grid(2, 2, 2) block(4, 4, 4)
- Reduction using global values array(512) on GPU, grid(1) block(1)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 10.8227 sec
- CPU = 1.8857 sec
- Step 3 = 6.47006 sec
- Step 4 = 1.74147 sec
- MemCopyH2D = 0.37493 sec
- MemCopyD2H = 0.15225 sec
- Steps:
- Version 3 (copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(8+8) and reduction for the max value and id of a block on GPU, grid(8) block(64)
- Reduction using global values and ids arrays(8+8) on GPU, grid(1) block(8)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 9.17189 sec
- CPU = 2.04448 sec
- Step 3 = 6.40427 sec
- Step 4 = 0.19378 sec
- MemCopyH2D = 0.37604 sec
- MemCopyD2H = 0.15332 sec
- Steps:
- Version 3.1 (copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(16+16) and reduction for the max value and id of a block on GPU, grid(16) block(32)
- Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 8.77189 sec
- CPU = 2.04448 sec (Data Transformation = 0.194 sec)
- Step 3 = 6.0427 sec
- Step 4 = 0.19378 sec
- MemCopyH2D = 0.37604 sec
- MemCopyD2H = 0.15332 sec
- Steps:
- Version 3.2 (allocate what you need at the beginning & copy what you need):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(16+16) and reduction for the max value and id of a block on GPU, grid(16) block(32)
- Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 8.34358 sec
- CPU = 1.58702 sec
- Step 3 = 6.02387s sec
- Step 4 = 0.20711ms sec
- MemCopyH2D = 0.37380 sec
- MemCopyD2H = 0.15178 sec
- Steps:
- Version 3.3 (allocate what you need at the beginning & copy what you need & and combine the GPU data):
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(16+16) and reduction for the max value and id of a block on GPU, grid(16) block(32)
- Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 8.06576 sec
- CPU = 1.466553 sec
- Step 3 = 5.99690 sec
- Step 4 = 0.20702 sec
- MemCopyH2D = 0.25319 sec
- MemCopyD2H = 0.078917 sec
- Steps:
- Version 4 (perfom batching with 1 stream per cpu-thread):
- For a batch of 4 vertices:
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(16+16) and reduction for the max value and id of a block on GPU, grid(16) block(32)
- Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16)
- Original point value on CPU concurrently with steps 3 & 4
- Time total = 7.18418 sec
- CPU = 0.946749 sec
- Step 3 = 5.94023 sec
- Step 4 = 0.20709 sec
- MemCopyH2D = 0.069697 sec
- MemCopyD2H = 0.020414 sec
- Batch size:✔

- Version 4.1 (perfom batching with #streams = batch-size within each cpu-thread):
- For a batch of 4 vertices
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(16+16) and reduction for the max value and id of a block on GPU, grid(16) block(32)
- Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16)
- Original point value on CPU concurrently with steps 3 & 4
- Version 4.2 (perfom batching with #streams = << batch-size within each cpu-thread):
- For a batch of 12 vertices with 4 streams
- Steps:
- Bounding box on CPU
- Grid creation on CPU
- Gridpoint values using global values and ids arrays(16+16) and reduction for the max value and id of a block on GPU, grid(16) block(32)
- Reduction using global values and ids arrays(16+16) on GPU, grid(1) block(16)
- Original point value on CPU concurrently with steps 3 & 4
- Time:
- lock time: 0.0190836 sec
- findCavityCells time: 0.178939 sec
- findUniqueVertices time: 0.215159 sec
- dataCollection time: 0.187204 sec
- boundingBox time: 0.0280833 sec
- grid time: 0.00122939 sec
- originalPointValue time: 0.12965 sec
- assignNewPoint time: 0.00165265 sec
- unlock time: 0.0117685 sec
- Total Cpu time: 0.77277 sec
- Distribution of Smoothing Time Per Vertex:✔
- Parallel CPU-wise:
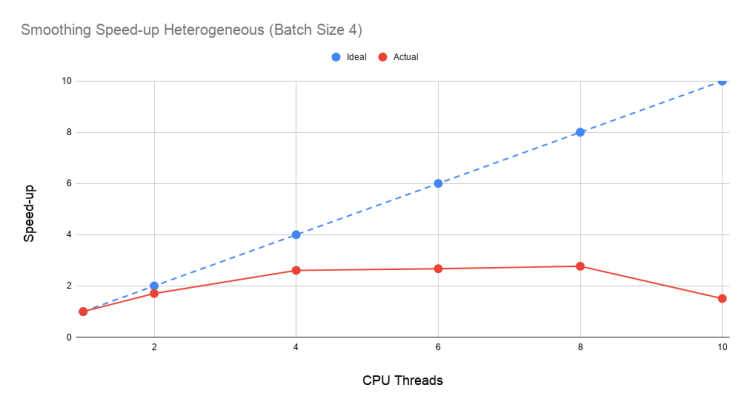
- Version 4:
- Speed-Up:✔
- Rollbacks-Time-Per-Thread:✔

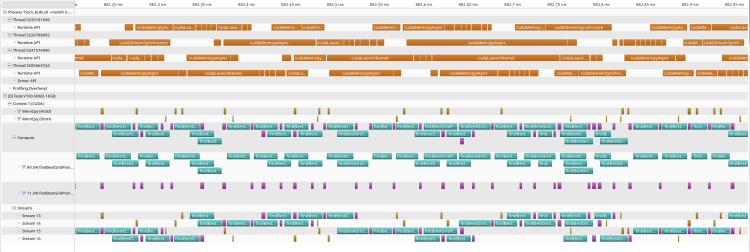
- Profiler: 4 cpu threads, 4 streams✔
- Speed-Up:✔
- Version 4.1:
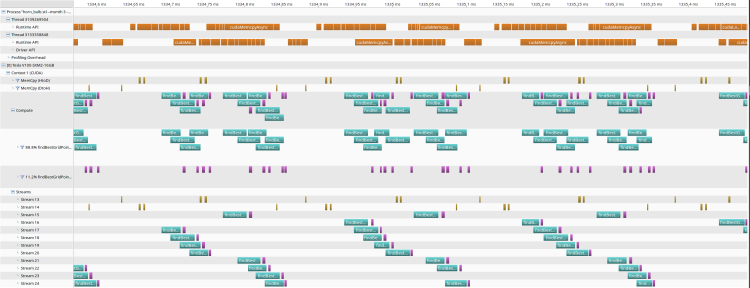
- Profiler: 2 cpu threads, 2(copy)+8(computation) streams✔
- Profiler: 2 cpu threads, 2(copy)+8(computation) streams✔
- Version 4.2:
- Rollbacks-Time-Per-Thread (#vertices = 28,217):✔

- Rollbacks-Time-Per-Thread (#vertices = 79,809):✔

- CPU (1 thread) 666 sec, CPU (32 threads) 28.29 sec
- Profiler: 2 cpu threads, 2(copy)+8(computation) streams✔
- CPU Time Histogram 1 thread:✔
- CPU Time Histogram 2 threads:✔
- Rollbacks-Time-Per-Thread (#vertices = 28,217):✔
- Version 4:
- Sequential CPU-wise:
- CPU version:


